

AI is not removing testing. It is changing who does it, when it happens, and what QA leadership is for.
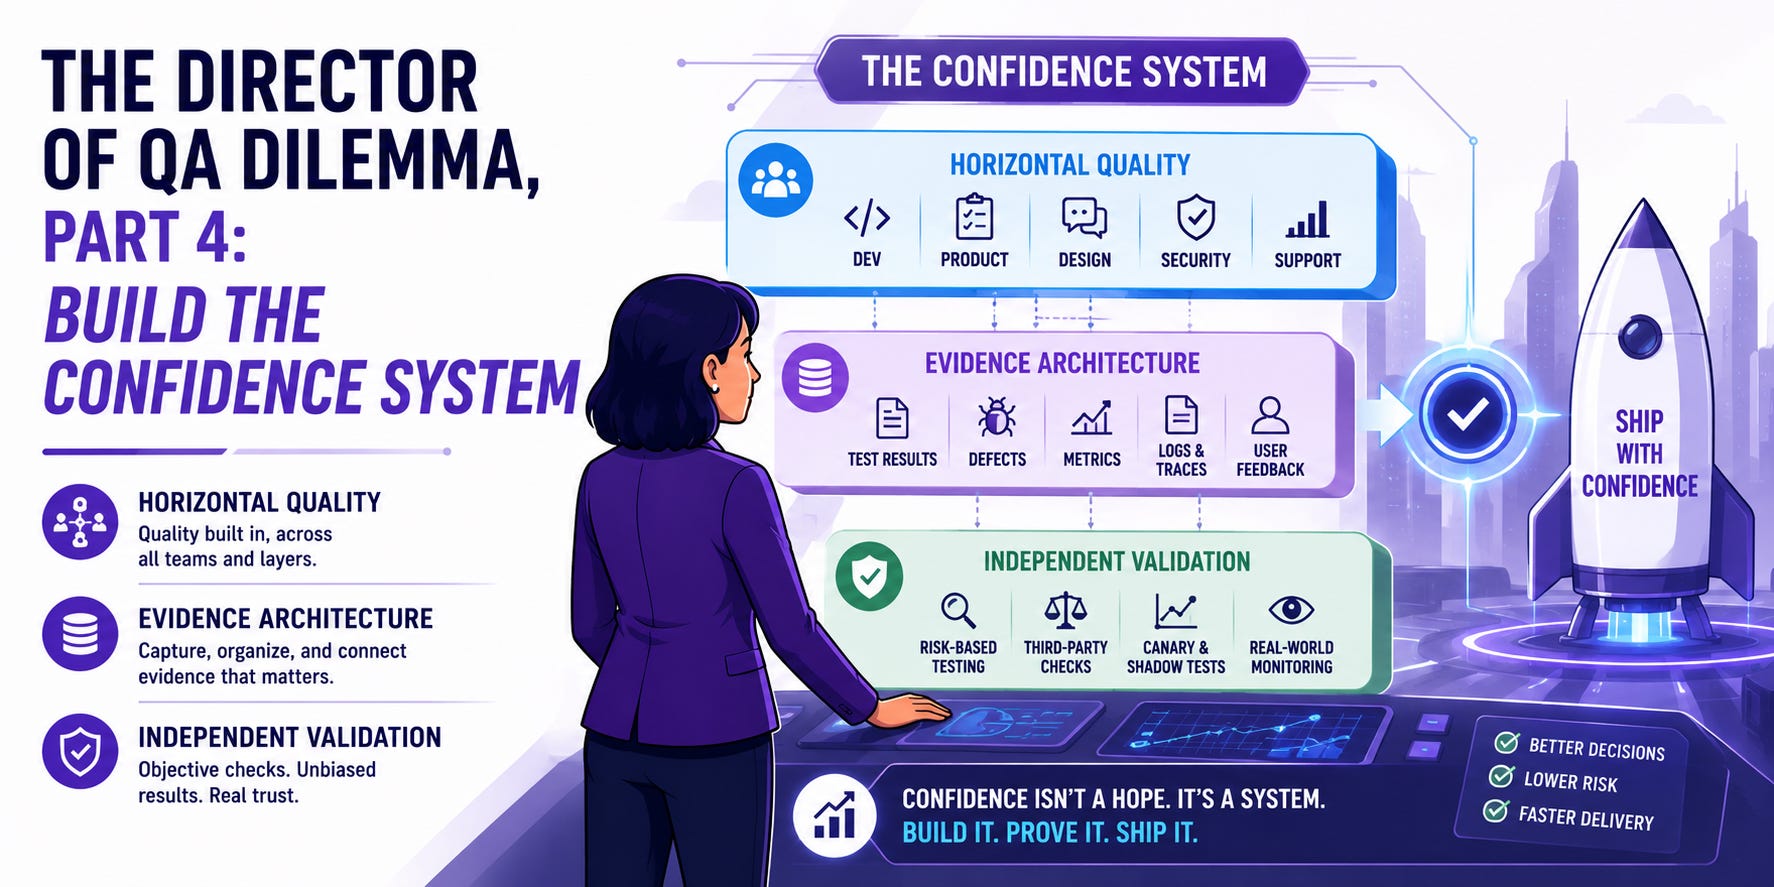
This is Part 4 of The Director of QA Dilemma, a five-part series about one larger transition: the Director of QA must move from defending testing activity to engineering the confidence that lets the company ship AI-generated software.
In the old model, QA could operate as a phase, a department, or a gate near the end of development.
In an AI-first engineering model, confidence has to surround the work.
Evidence generation begins when the coding agent starts planning. It continues while the agent changes code, chooses dependencies, calls tools, generates tests, and runs the software. It continues through code review, staging, shadow traffic, canary release, production monitoring, incident response, and the next model or prompt update.
No single team manually performs all of this work. No final regression cycle can compensate for missing evidence throughout the rest of the system.
The QA organization should help define the skills, policies, evals, observability, release thresholds, and independent review routes used across the development lifecycle.
This is less about controlling every test and more about designing the company’s confidence system.
The Measurement System Becomes the Product
The most important platform owned by the future QA organization may not be a test framework. It may be the system that explains why the company should trust a change.
That system needs to preserve:
what changed
which models and prompts were used
what context the agents saw
which tools they called
what scenarios ran
which users and risks were represented
how outputs varied
what failed
where reviewers disagreed
what evidence is still missing
It must distinguish a deterministic product defect from expected model variation. It must compare versions without pretending that one aggregate score describes quality. It must surface serious failures that averages hide. It must connect production incidents back to permanent eval cases.
Most importantly, it must end in a decision.
Ship. Canary. Hold. Roll back. Escalate. Gather more evidence.
A report that produces percentages without helping someone make one of those decisions is not a confidence system. It is decoration.
Building this system requires automation, statistics, product judgment, risk analysis, human review, observability, and communication. It is broader than the old QA mandate, but it is also much closer to what executives always wanted QA to provide.
Not more tests. Confidence.
Independent Evidence Still Matters
AI collapses implementation and testing into the same harness, but independent evidence becomes more important, not less.
The coding agent should test its own work continuously. That feedback is fast and useful. It is also incomplete.
The agent that chose the design may repeat the same assumptions when it chooses the tests. The model that generated the code may share blind spots with the model judging it. The platform selling the model may optimize its tools around its own ecosystem, benchmarks, and business interests.
The Director should require strategically independent checks. Depending on risk, that can mean:
deterministic validators
production comparisons
human-reviewed samples
adversarial scenarios
a different model family
a separate evaluation agent
an external quality platform
Not every check needs a separate organization or vendor. Independence should follow risk. A button-label change does not need the same review structure as a payment workflow, medical recommendation, autonomous action, or data-access policy.
The principle is simple: the higher the consequence, the less comfortable the company should be with the creator grading its own work.
Quality Becomes Horizontal
The new QA organization does not wait at the end of development. It puts confidence mechanisms into the places where product behavior is created.
That includes the coding agent’s instructions, its permissions, the examples it sees, the checks it runs, the traces it preserves, the thresholds that govern releases, and the production signals that send the system back for review.
The Director does not need to own every tool. The Director needs to own the standards that make the tools trustworthy together.
This also changes how success is reported. Test counts and automation percentages become weak proxies. Better measures include:
time from change to credible release evidence
meaningful risk coverage
severe failures detected before broad exposure
rollback readiness
production incidents converted into regression evidence
reviewer agreement and calibrated disagreement
decision latency
evidence cost relative to consequence
The point is not to replace one dashboard with a newer dashboard. The point is to build a measurement system connected to real release decisions.
Part 5, Lead Before They Work Around You, closes the arc with the political and career stakes of waiting, and the emerging mandate of the Director of Confidence Engineering.
Learn more in the Testing AI knowledge guide.
Build the First Version of Your Confidence System
IcebergQA combines experience from Microsoft and Google-scale testing with years spent building AI testing startups and validating AI-generated behavior. We help teams move beyond test counts and design the evidence system that their coding agents, releases, and leaders actually need.
In a 30-day AI quality transformation sprint, we can define your highest-risk decisions, connect AI-generated tests with independent checks, establish useful evals and production signals, and create release evidence that ends in a clear action: ship, canary, hold, roll back, or investigate. You leave with a working confidence loop, not another abstract framework.
—Jason Arbon, IcebergQA